


Data is both ubiquitous and mysterious.
It’s a block of binary. A bunch of bytes. Big deal?
Data is the WD-40 that lubricates the gears of our applications. The colourless mana that converts network packets to domain objects, files to visible UIImages, or a WebSocket stream into live-chat.
Big deal.
For legacy reasons, Data lives outside the Swift standard library, in Foundation.
Foundation and swift-foundation
The Foundation library is ancient by technological standards, with roots all the way back to the NeXTSTEP operating system that underpins macOS today. It provides basic functionality for all apps, such as data management, text processing, date and time tools, and networking.
In 2022, swift.org announced an open-source, pure-Swift re-write of Foundation in The Future of Foundation. This was motivated by a push towards multi-platform Swift, untethered from Darwin. Swift developers can leverage familiar Foundation functionality while writing systems for the cloud, embedded devices, Windows, and maybe even Android!
The swift-foundation source code is already used in production on Apple platforms, as part of the ubiquitous Foundation umbrella framework. It lives alongside legacy, non-rewritten, C and Objective-C code.
Today, we’re going to look under the hood of swift-foundation and understand exactly how Data is implemented.
How Foundation is implemented
First, let’s jump straight to Data.
Right at the top, we see the secret sauce of a cross-platform rewrite:
Lower-level shared system libraries.
A multiplatform swift-foundation is achieved by aliasing C functions common among most computing platforms, such as malloc() and free().

While the implementations are, as you can see, different for different platforms, the core API for libc, the C standard library, is universal. This is the beauty of a ubiquitous language like C forming the backbone of virtually all computing: systems have a common API for implementing common behaviours like allocating memory on the heap, freeing said memory, and comparing bytes.
This is a common theme across swift-foundation and, for that matter, many cross-platform libraries. Platform-specific implementations import the same standard library APIs.
syscalls and malloc
Let’s take a closer look at just one of these functions, on just one platform, to get a deeper picture of what’s going on under each platform implementation.
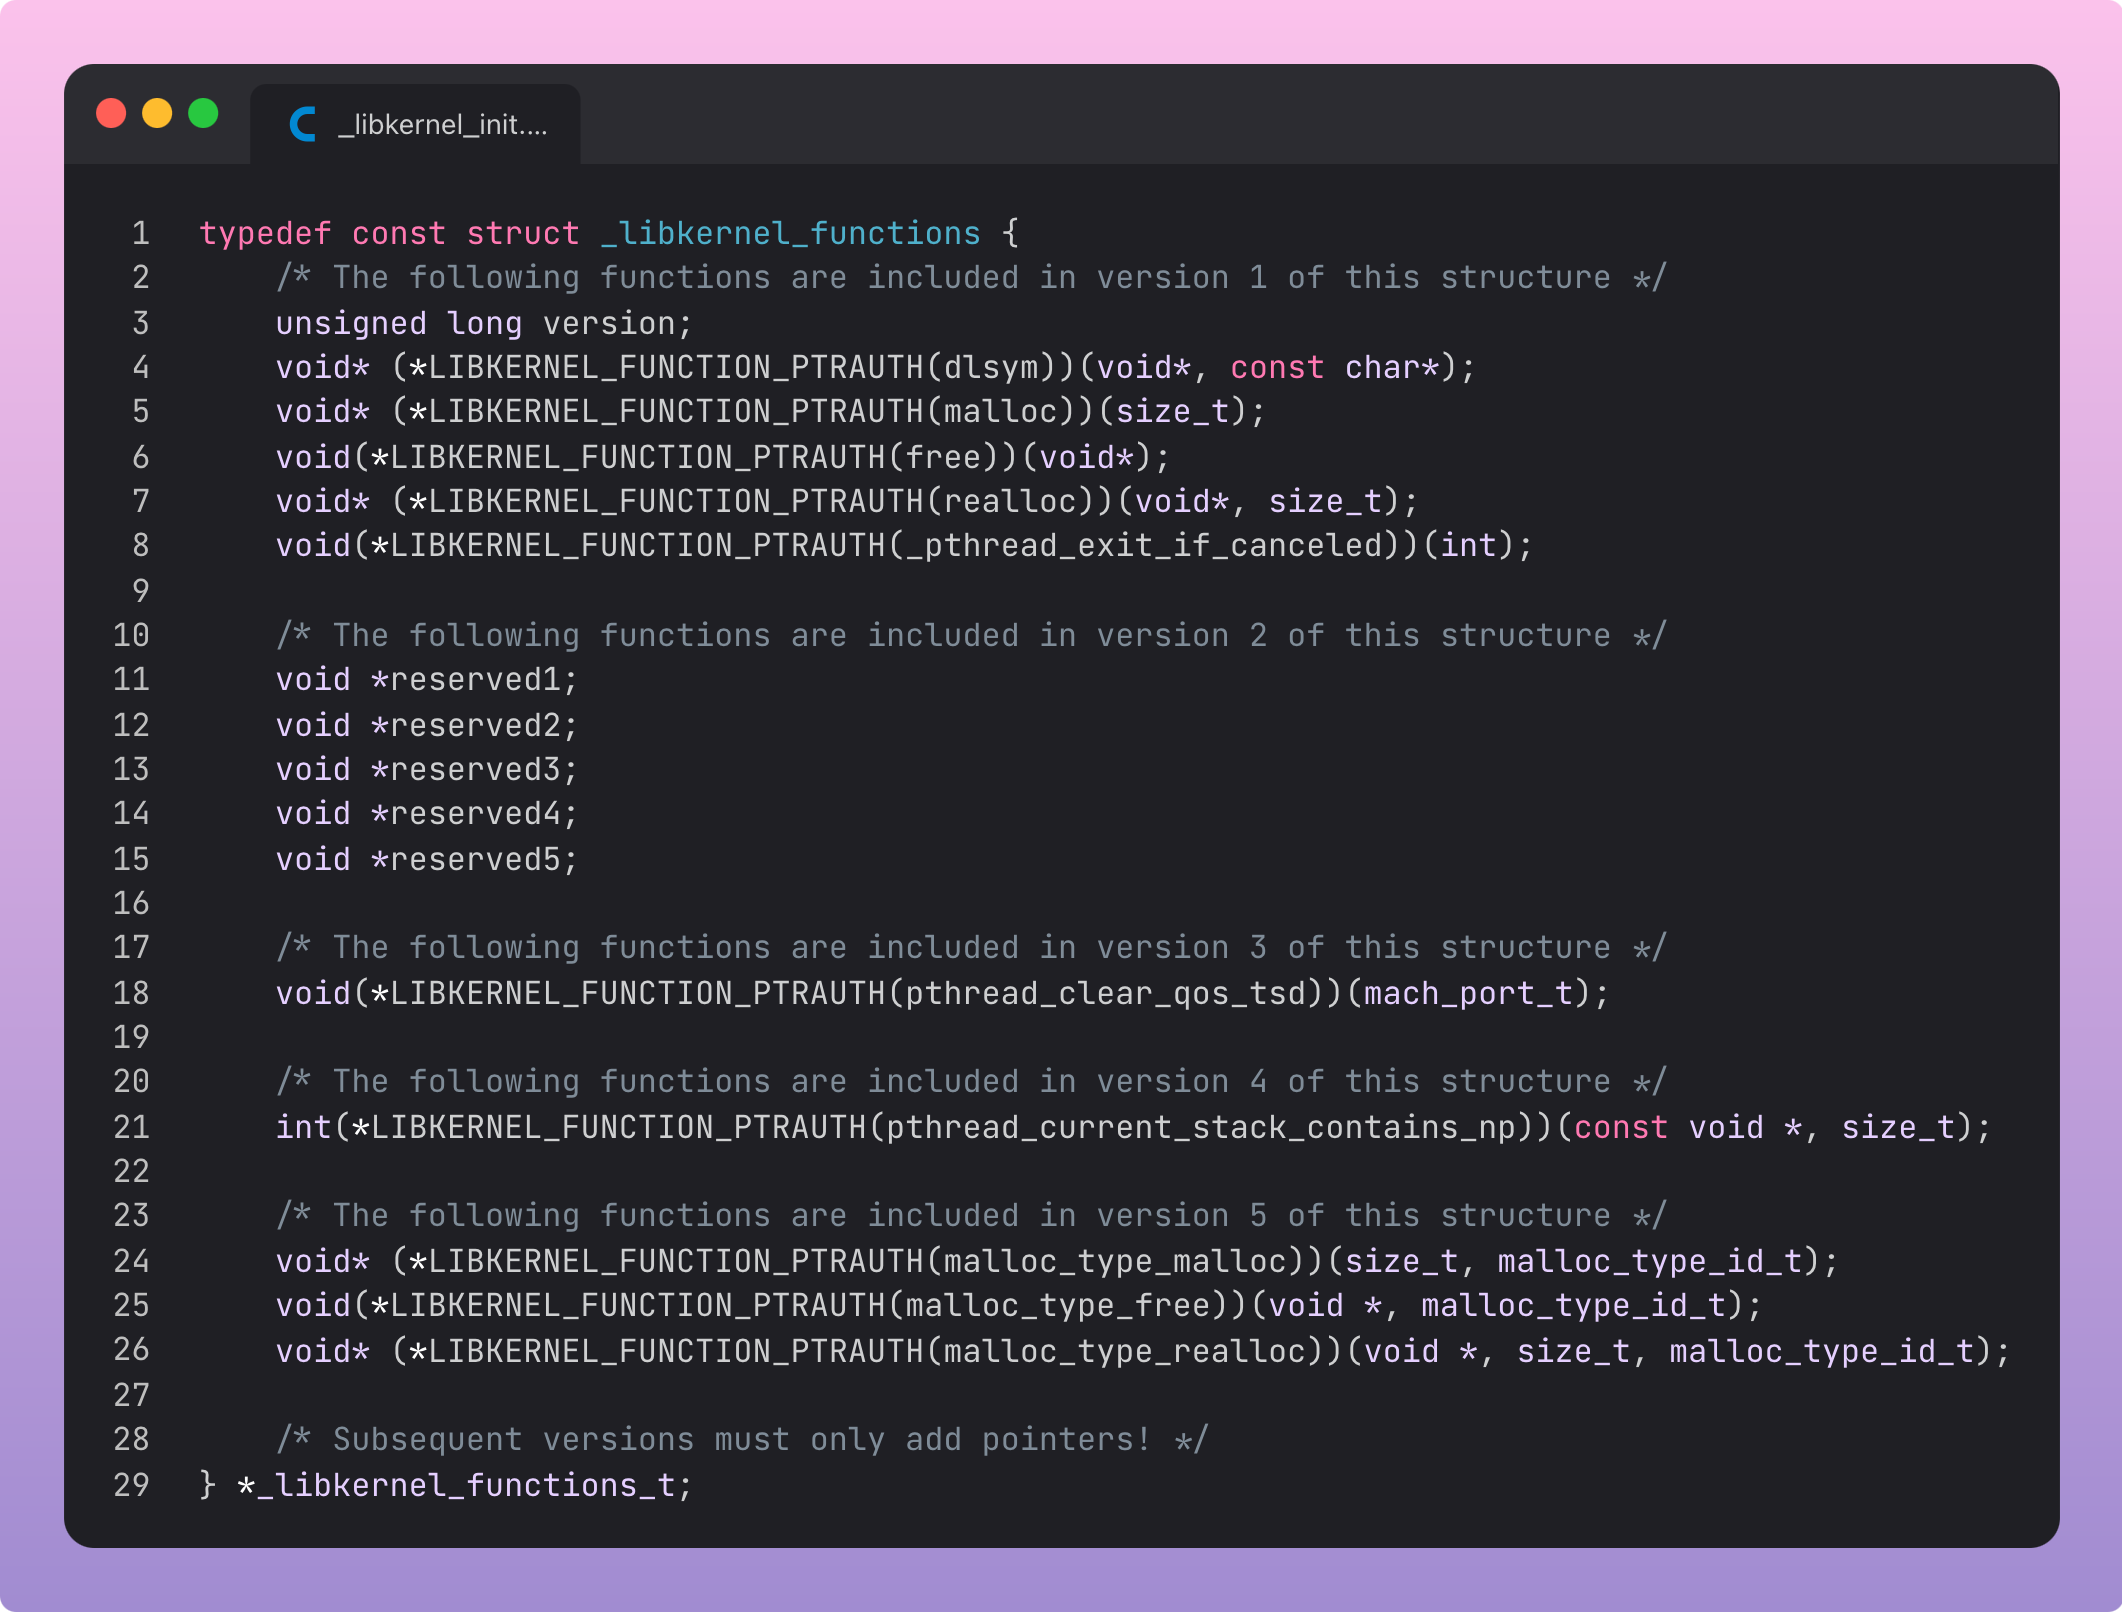
On Darwin-based Apple systems, the malloc() C function eventually leads down to a syscall into the Mach microkernel, part of the XNU kernel which underpins all Apple platforms. Here’s a partial list of these syscalls in libkernel.
The syscall underneath malloc() invokes the virtual memory subsystem to allocate a block of memory on the heap and return a pointer.
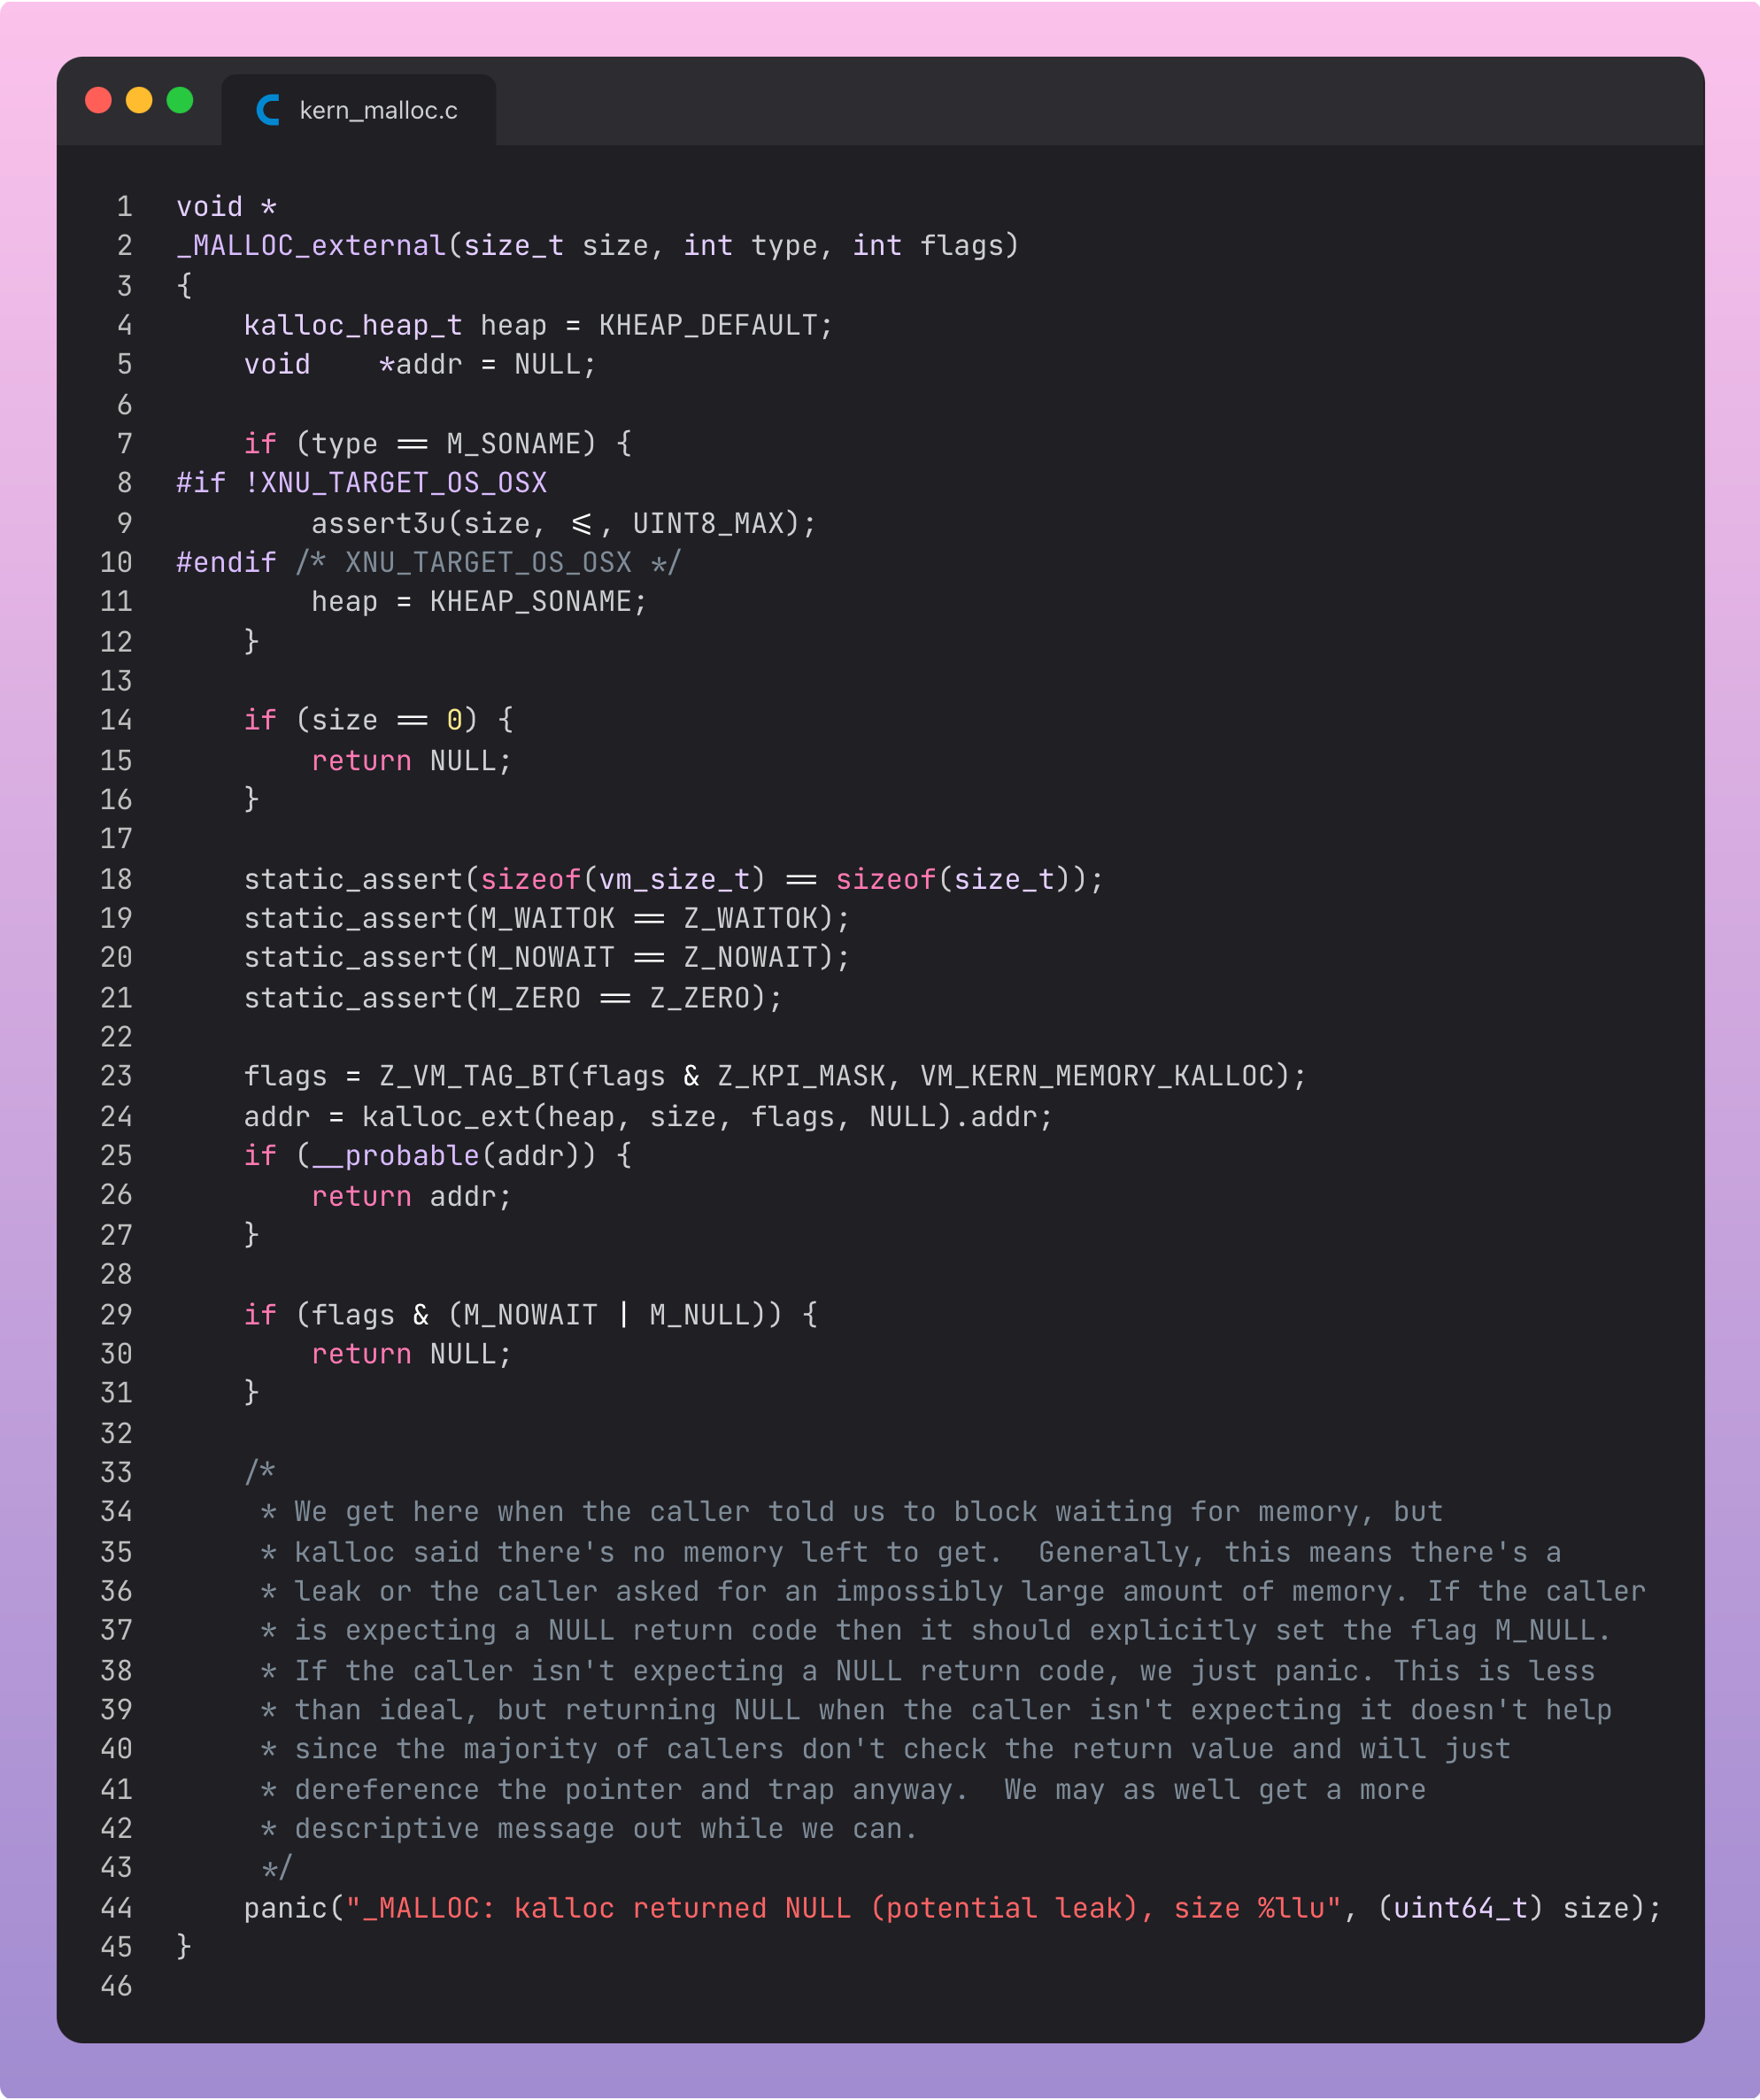
With this single very deep example, we’ve illustrated that basic system-level functionality is implemented for each operating system, with a common API that can be used across all of Foundation.
Therefore, common functionality across the C standard library serves as Foundation’s, uh, foundation.
Now let’s get back to Data.
Data
We can find Data in swift-foundation/Sources/FoundationEssentials/Data/Data.swift.
Data is a lightweight Swift struct with two main jobs:
Manage a pointer to a memory buffer on the heap
Implement various optimisations for performance
Seriously, pretty much everything it does is one of these two things.
There’s beauty in this simplicity.
This simplicity means that even if you’re new to spelunking into open-source system frameworks, it can be relatively understandable.
The Declaration
600 lines of code in, and we land at the actual struct declaration.
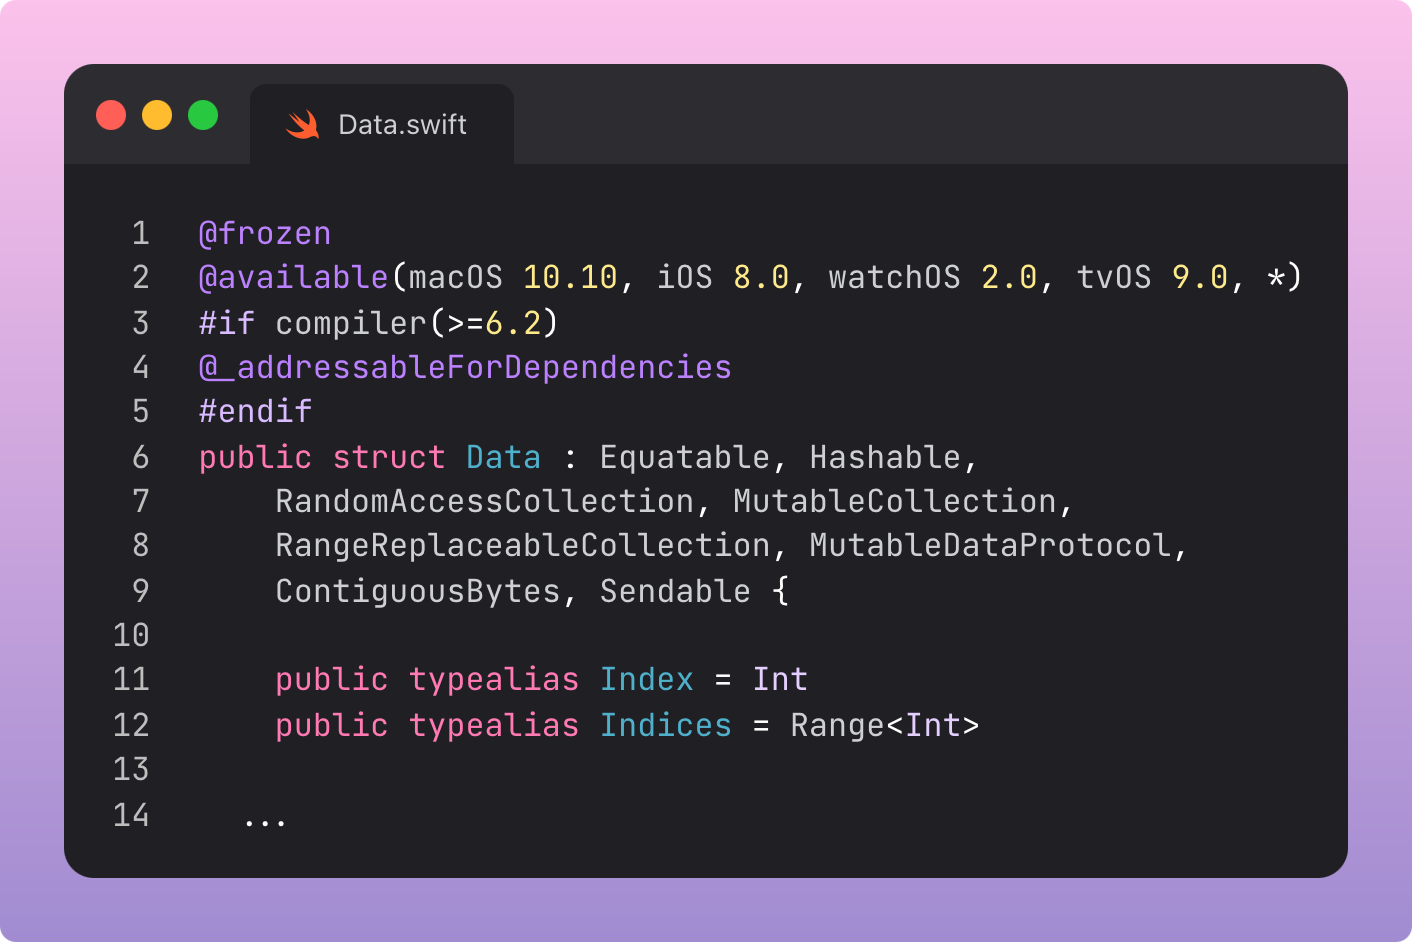
That’s a lot of conformances:
Equatable, Hashable, RandomAccessCollection, MutableCollection, and Sendable are pretty commonplace library protocols.
RangeReplaceableCollection, which supports replacement of any sub-range of its elements with new elements.
MutableDataProtocol, which inherits from DataProtocol. This provides access to an underlying buffer of (lowercase D) data.
ContiguousBytes ensures the type offers access to the underlying raw byte buffer. “Contiguous” means the bytes all lie in a single unbroken block, with all the bits touching.
A pointer to the heap
This is really the main function of Data (big D). Pointing at some data (small d).
Perhaps confusingly, the data doesn’t actually live in Data. It’s all on the heap, referenced by a pointer.
This is actually one of the most basic, ubiquitous optimisations across all of computing.
Instead of working with an enormous 500MB block, which takes milliseconds and many cache pages to even read from RAM, we can use an address pointer that fits in a single CPU register.
This underlying storage of Data’s data is contained within the private __DataStorage type.
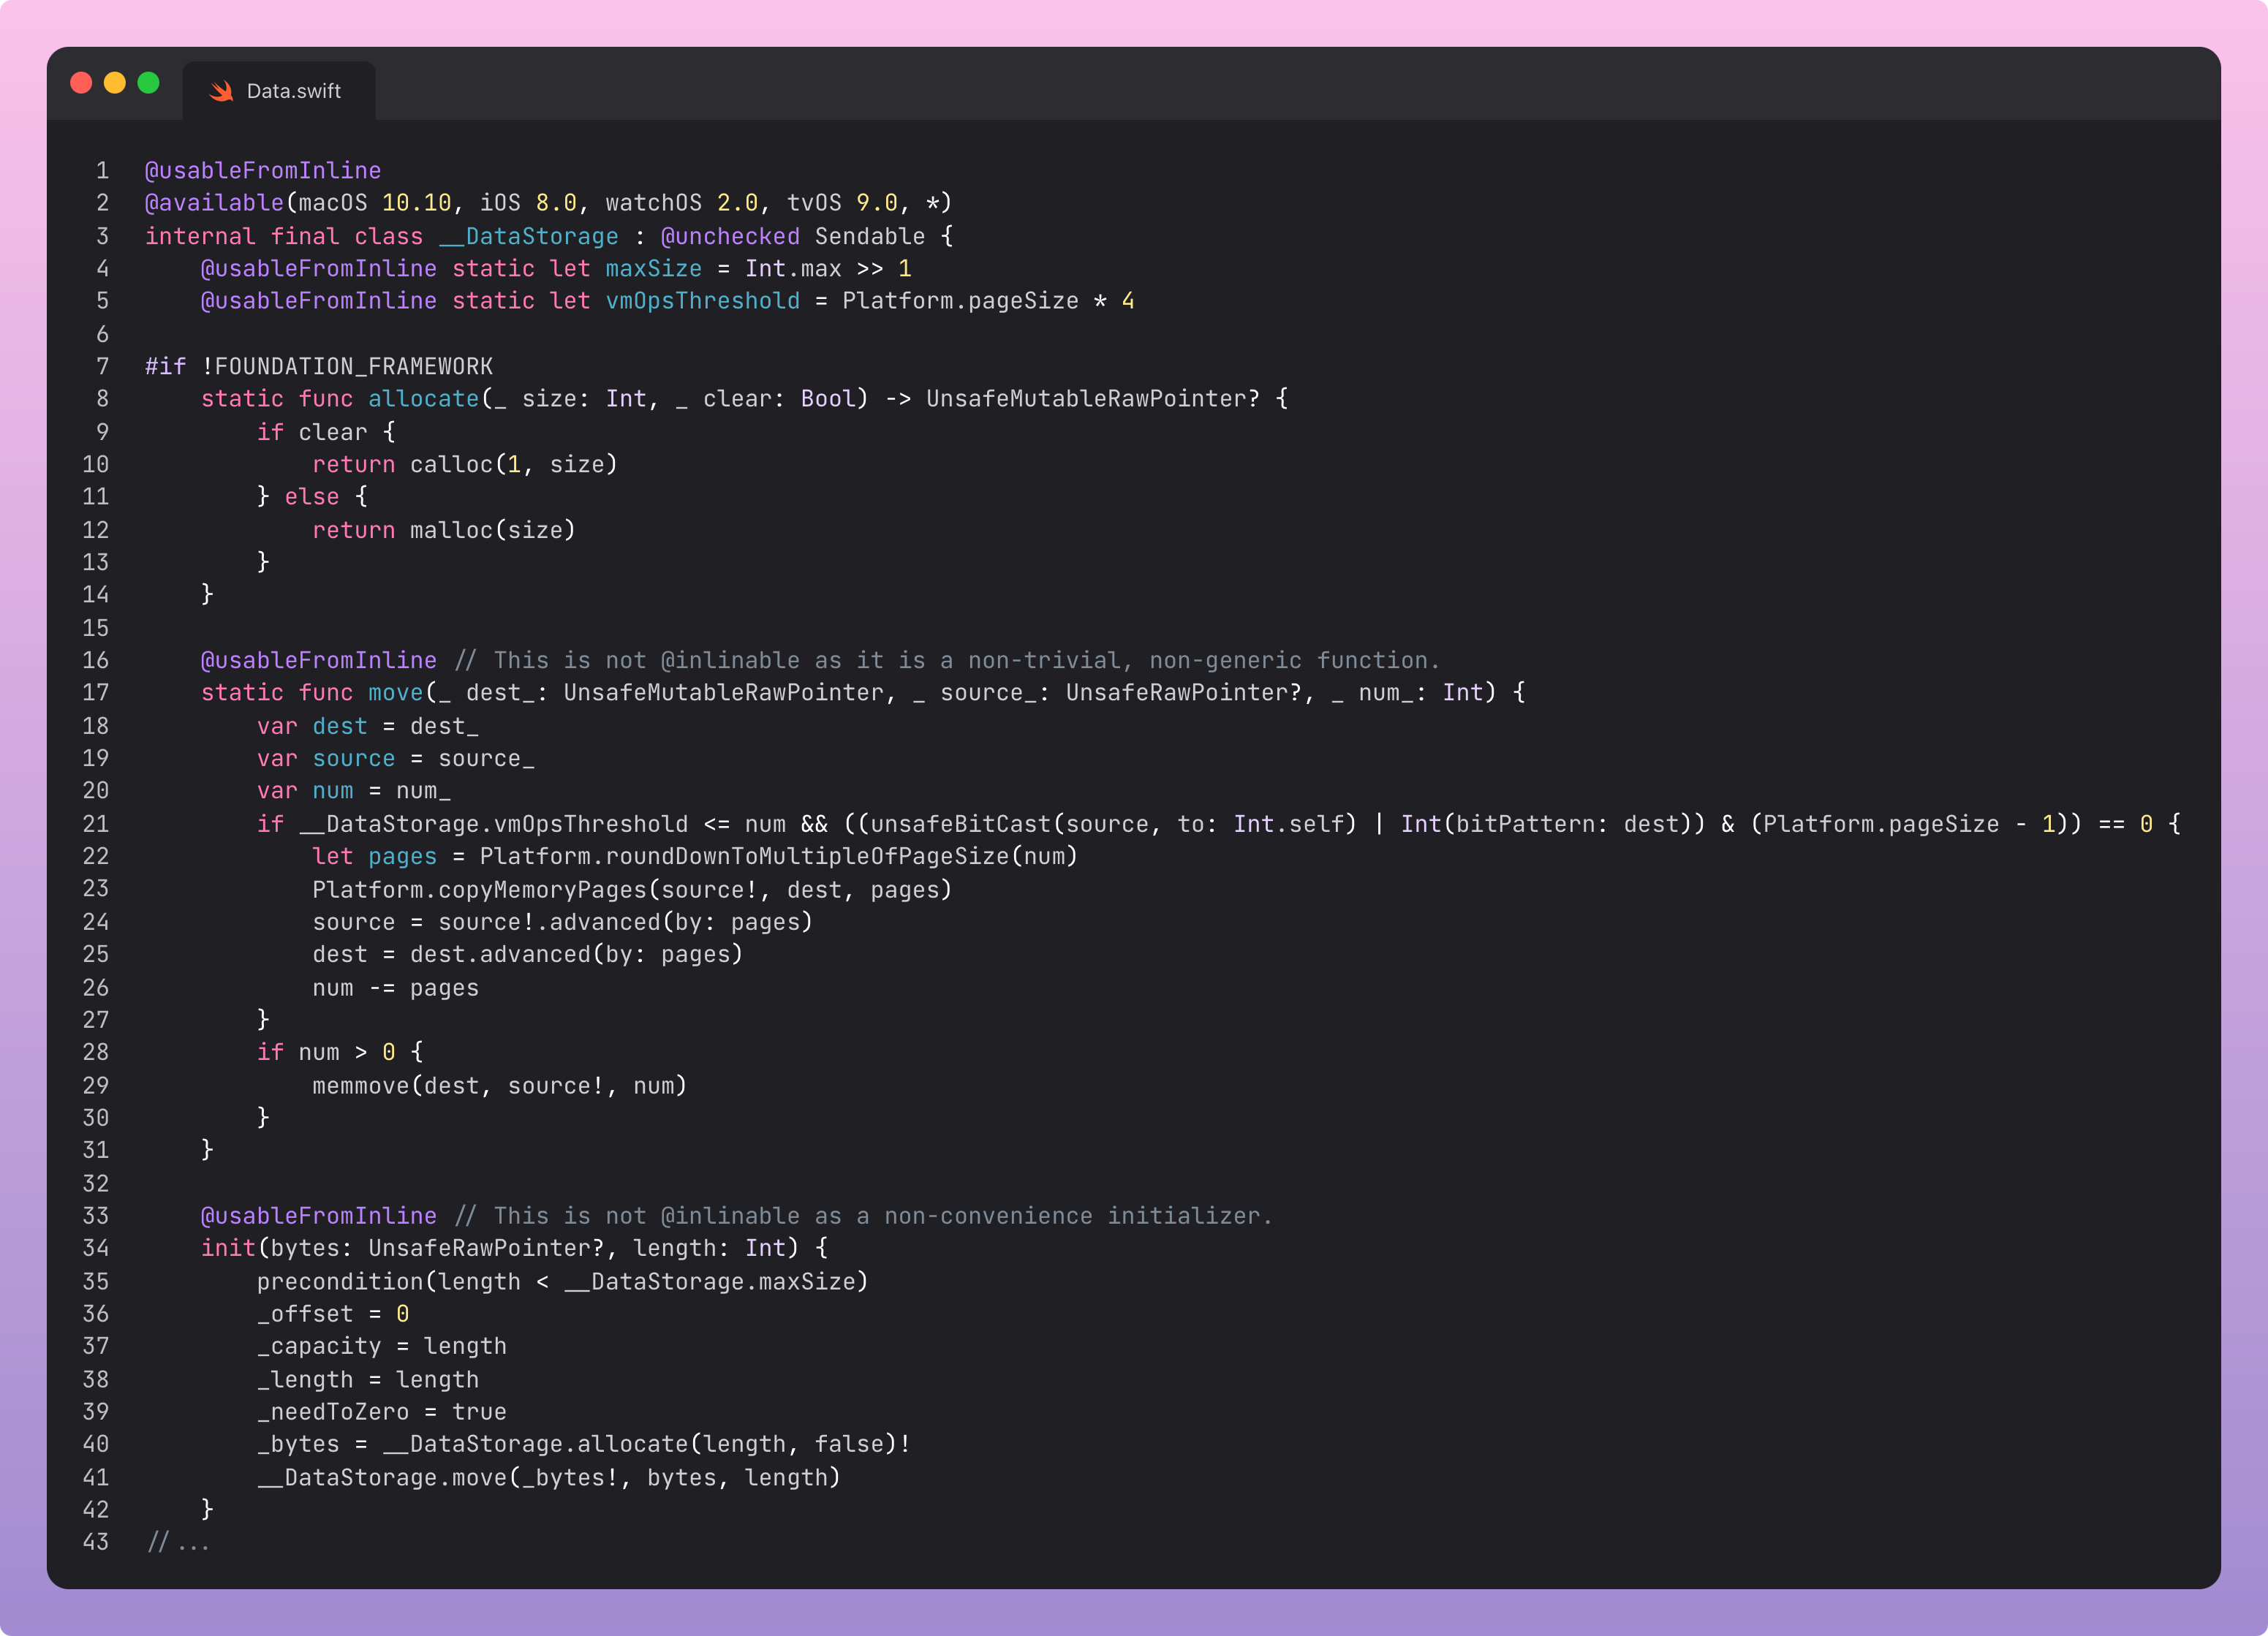
__DataStorage inits using an UnsafeRawPointer, a simple C pointer, to the bytes it will be storing. It sets the relevant metadata such as offset, capacity, length, and of course the bytes.
It allocates this memory on the heap using malloc() and returns a pointer to the new memory. It copies the original data to the memory address of this pointer using memmove() C library function.
The offset property here is handy for efficiency, because it allows a slice of the data (remember it’s a RangeReplaceableCollection!) to act as a window into a larger block of data.
__DataStorage also contains a deallocator that frees the memory in the buffer. Normally this is the C free() method, but some blocks may need platform-specific custom cleanup, for example Darwin’s vm_deallocate that cleans up virtual memory.
__DataStorage also contains my old friend and writing companion, isKnownUniquelyReferenced, as it implements the copy-on-write optimisation. Any underlying storage is shared between any references unless it gets mutated.
So now we’ve seen where Data actually stores memory on the heap. In __DataStorage. What are the rest of the 3022-odd lines of code?
Optimisations, my friend.